Designing a Private AI Governance Framework for Self-Hosted LLM Deployments
Designing a Private AI Governance Framework for Self-Hosted LLM Deployments The New Imperative: Governing Your
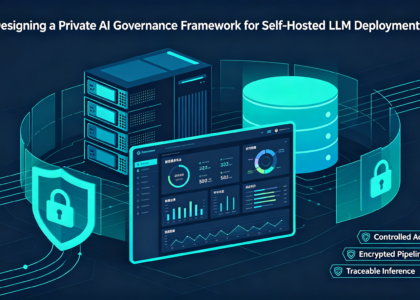
Designing a Private AI Governance Framework for Self-Hosted LLM Deployments The New Imperative: Governing Your
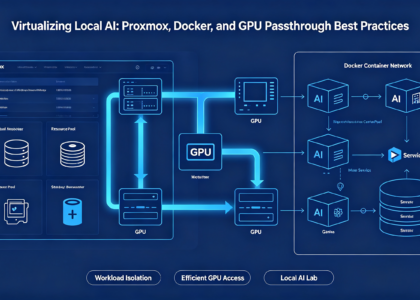
Virtualizing Local AI: Proxmox, Docker, and GPU Passthrough Best Practices The Infrastructure Evolution: From Single
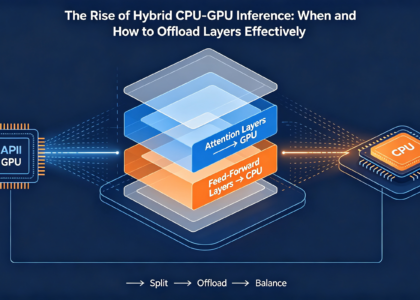
The Rise of Hybrid CPU-GPU Inference: When and How to Offload Layers Effectively The Efficiency
NVMe vs. SATA in Local AI: How Storage Choices Impact Your Model Loading Times The
Ollama Mastery 2026: Advanced Tips for Multi-Model Workloads and API Serving The Evolution from Single