Scaling Your Home AI Lab: From Single GPU to Multi-Node Distributed Inference
Scaling Your Home AI Lab: From Single GPU to Multi-Node Distributed Inference The Evolution from
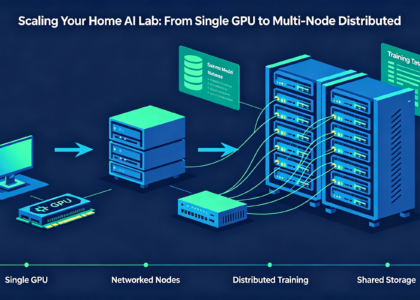
Scaling Your Home AI Lab: From Single GPU to Multi-Node Distributed Inference The Evolution from
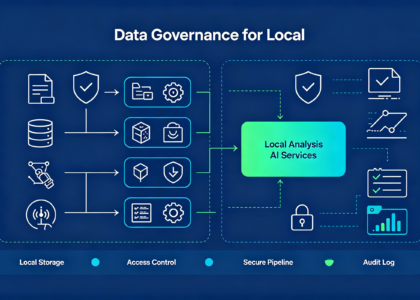
Data Governance for Local AI: Keeping Your Datasets Compliant and Secure in 2026 The
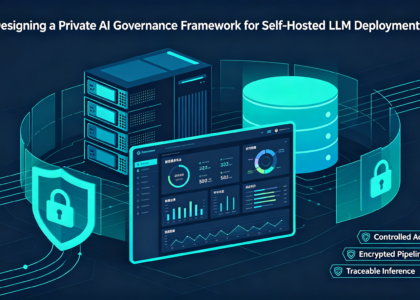
Designing a Private AI Governance Framework for Self-Hosted LLM Deployments The New Imperative: Governing Your
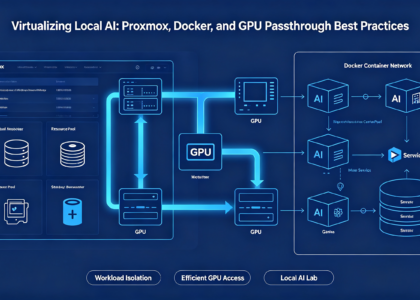
Virtualizing Local AI: Proxmox, Docker, and GPU Passthrough Best Practices The Infrastructure Evolution: From Single
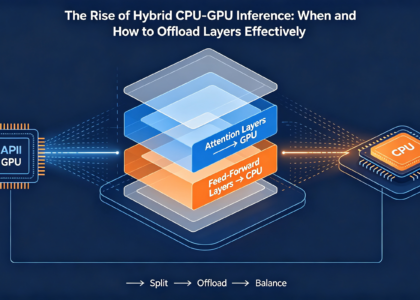
The Rise of Hybrid CPU-GPU Inference: When and How to Offload Layers Effectively The Efficiency
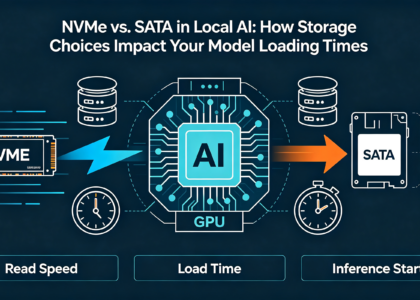
NVMe vs. SATA in Local AI: How Storage Choices Impact Your Model Loading Times The
Ollama Mastery 2026: Advanced Tips for Multi-Model Workloads and API Serving The Evolution from Single
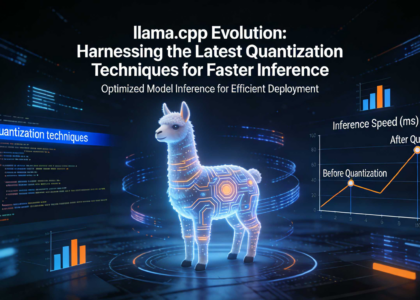
The Silent Revolution in Model Efficiency While flashy new multi-modal models grab headlines, a quieter,
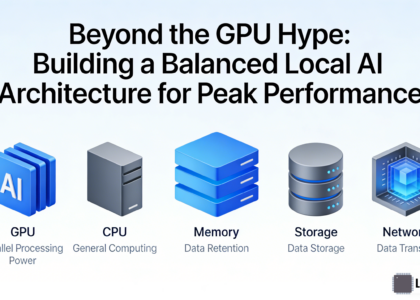
The Hidden Bottleneck in Your AI Workstation The buzz from CES 2026 is unmistakable: NVIDIA’s
The Silent Revolution Beyond the Cloud As CES 2026 fades from the headlines, the true